Now Reading: South Asians missing from 86% of global genetic health data
-
01
South Asians missing from 86% of global genetic health data


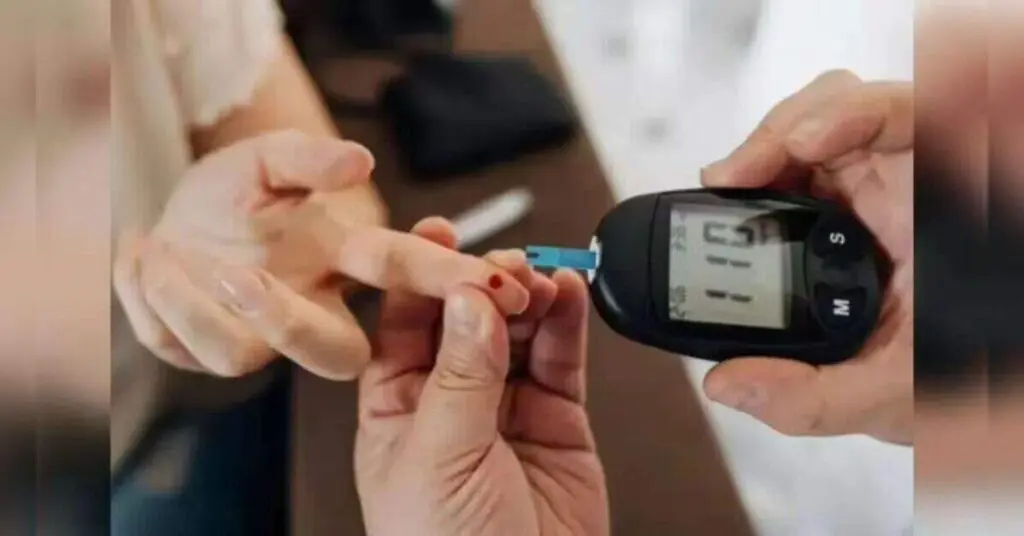
More than 86% of participants in genome-wide association studies since 2005 have been of European ancestry, while South Asians account for less than 1%, according to the NHGRI-EBI GWAS Catalogue. This data gap means AI tools and polygenic risk scores built on European datasets are less accurate for South Asians, who face higher rates of type 2 diabetes, cardiovascular disease and asthma.

Researchers warn that single-cell atlases used to train AI models also overwhelmingly represent European populations. Yale public health dean Bhramar Mukherjee said more than 20% of the world is being neglected, denying them the human right to attain maximal possible health. The GenomeIndia Project aims to capture the country's genetic diversity, but much South Asian data remains absent from global biobanks like the UK Biobank.
Indian Opinion Analysis
Polygenic risk scores and AI diagnostics trained on European genomes risk misclassifying millions of South Asians who face earlier and higher rates of type 2 diabetes, cardiovascular disease and asthma. India alone expects 125 million diabetes patients by 2045, yet less than 1% of genome-wide study participants are South Asian. The GenomeIndia Project, capturing the country's vast genetic diversity, remains a modest counterweight to biobanks like the UK Biobank. Without systematic inclusion, clinical thresholds and drug targets derived from European data will continue to miss the mark for India's population. Watch for whether Indian funding agencies mandate South Asian data inclusion in future AI diagnostic tools approved by the CDSCO.
Source: thehindu.com
This story was synthesised by AI from the source linked above. Methodology and corrections.